BrontoDB: The Polymorphic Database for Observability
Marco Aquilanti
Lead Software Engineer
David Tracey
CTO
Introduction
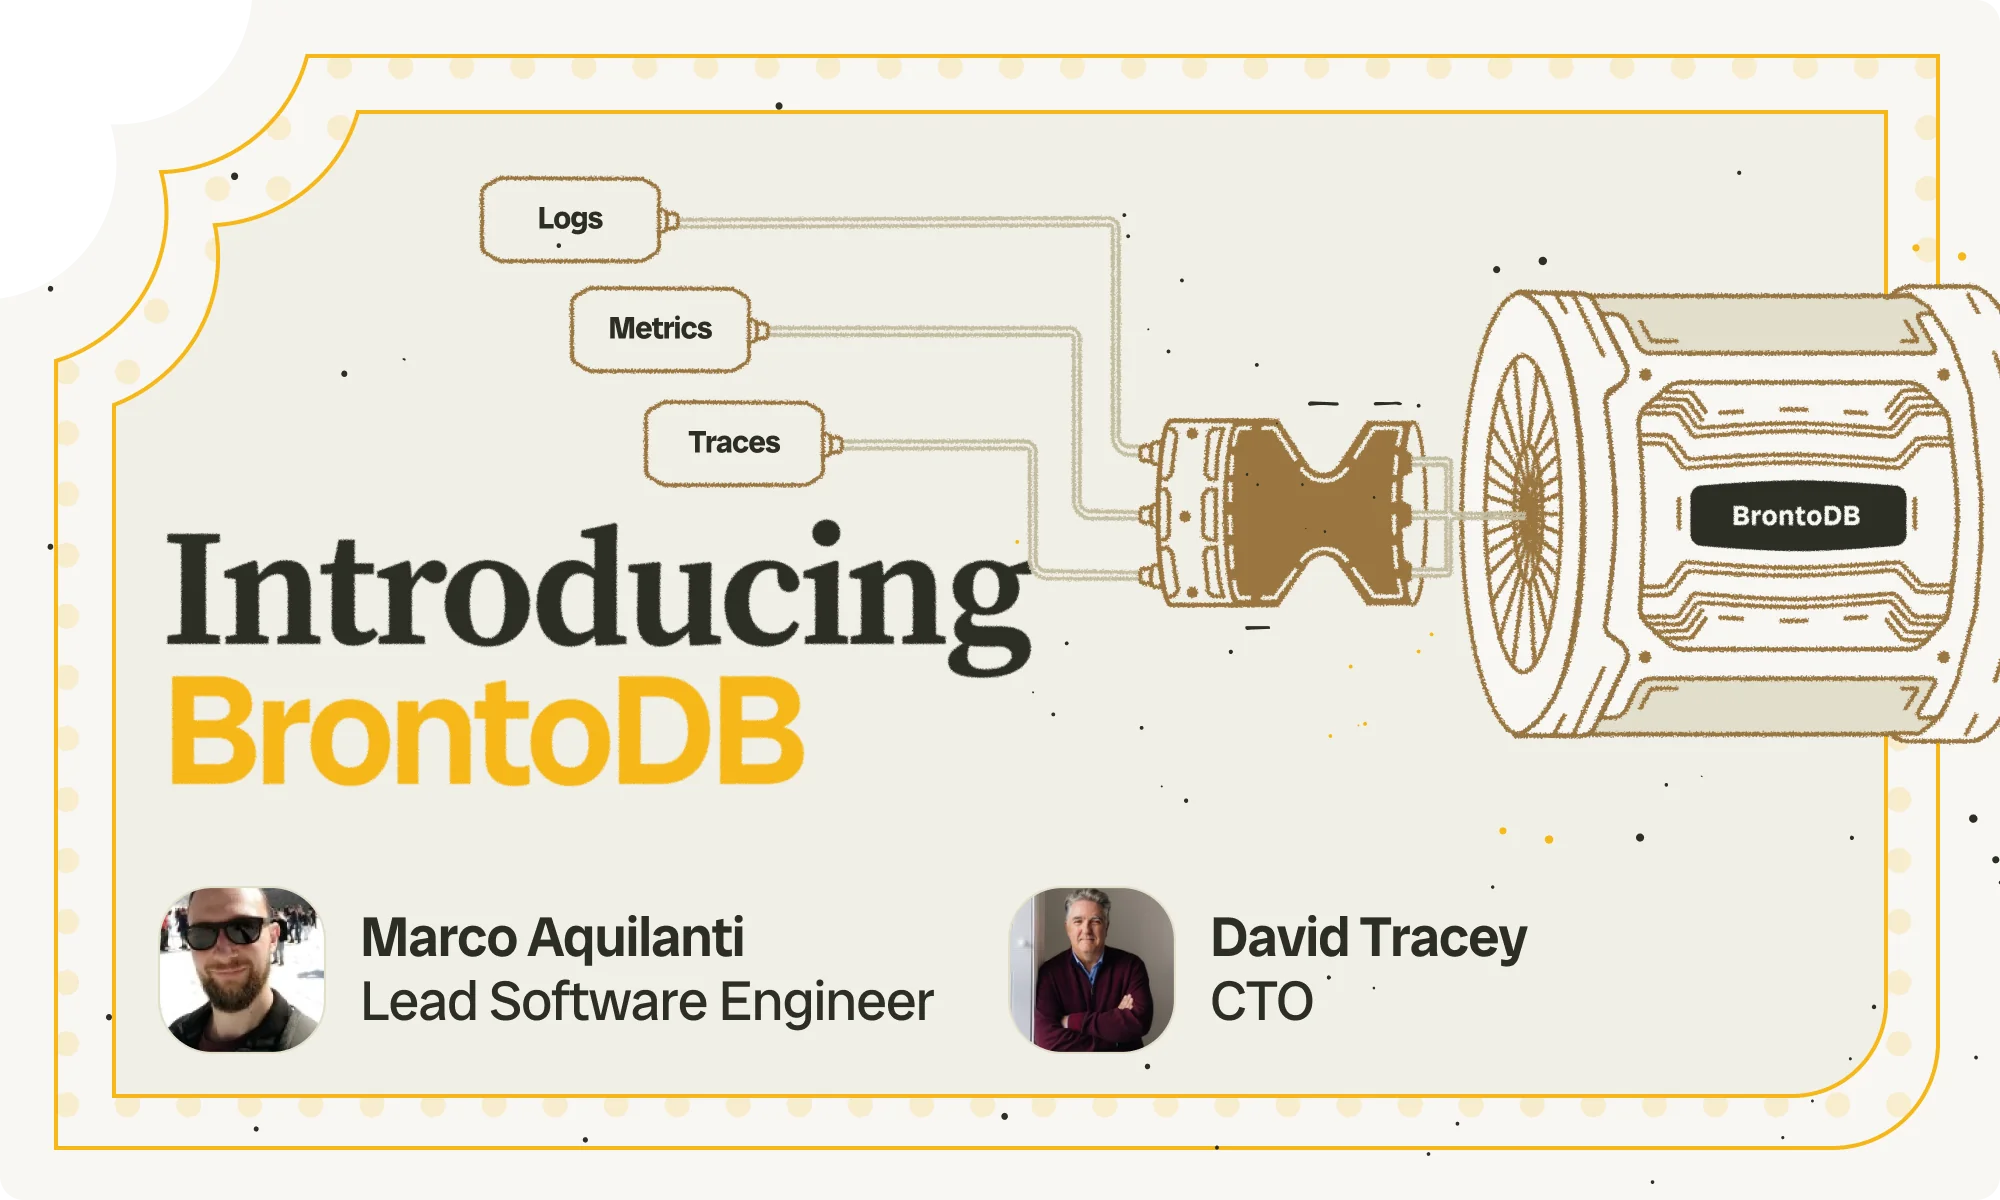
This blog will introduce you to BrontoDB. We’ll start the blog by answering a few typical questions we get about our approach, and then we’ll introduce the key parts of the architecture and the architectural principles we follow. Finally, we’ll present search performance metrics and outline the benefits you get by using Bronto.
What are the issues with Observability Data?
The first thing to note is the Multidimensional Nature of observability data as it includes data in the form of Logs, Traces and Metrics. It may be structured, unstructured, semi-structured data and may be high cardinality and/or include sparse keys – all of which can be hard for general purpose databases to handle.
Add to this the fact that it is used in a Changing Environment, where the structure of data changes or the searches change. Structure can change by the addition or removal of keys without warning when developers add new fields to debug specific issues or third-party systems change their log formats without notice – this may break dashboards or alerts or even cause the data to be dropped. Search patterns are often unpredictable and change – some data may be stored and ignored for months, then heavily searched when an incident or a new request arrives. Other data is critical to the business and is intensively monitored and processed for analytics on a regular basis.
As if this was not enough, there is a Growing Volume of data, driven by the growth in traffic, new systems and the high volume of data produced by AI workloads – meaning there is more data to store and search and that data should be retained longer to allow historical analysis. This growing volume of data may occur gradually or as a sudden step increase or a spike, challenging the observability platform to scale appropriately and quickly.
What is BrontoDB?
BrontoDB powers the Bronto platform and is one store for all your observability data – Logs, Traces & Metrics in one place with a unified experience where signals can be easily correlated – it is purpose-built for this specific type of data – and provides teams with access to over 100x more data with always fast search. BrontoDB fully supports OTel as well as any other observability data formats (legacy, syslog, unstructured etc.) and works with all commonly used data collectors (OTel, Fluent Bit, etc. see our docs for more). Beyond configuring collectors to send your data, Bronto requires no configuration or management. It automatically parses and indexes your data, is fully managed SaaS, and search is always fast with 12-month default retention.
BrontoDB is an object-store-native database – based on the core principle of separating storage and compute, combined with a serverless architecture. BrontoDB is unique insofar as it can automatically adapt to changing data and queries maintaining always fast search with an always cost-efficient solution.
It uses custom indexing & columnar formats, which we designed specifically for logs, traces and metrics, each optimized for the particular characteristics of the different data types and queries, e.g. handling the often messy structure of logs and traces or the high cardinality of metrics data.
These columnar formats were designed to compress extremely well enabling cheap data storage. For example, logs and traces, including their associated indexes, compress typically by 10x and up to 68x, while metrics compress by up to 330x – by taking advantage of repeated values and timestamps sequences. Indexes are created automatically and stored for all logs & traces enabling both fast and efficient search.
Bronto is unique in how it combines the benefits of automatically parsing, indexing and self-tuning the system. Bronto automatically parses and indexes so that users do not have to ‘configure’ the system or ‘know’ how/what to index up front. Instead the system performs this dynamically and adapts indexing appropriately as the shape of data changes. Our adaptive indexing picks the right technique for each field based on your data and query patterns, so searches skip the vast majority of data rather than scanning it. That keeps search fast and costs predictable as volumes grow, unlike platforms that either require you to manage indexes yourself or rely on brute-force scan. Bronto provides fast search for both structured and unstructured data - from free-text hunts for a needle in a haystack, to large analytical aggregations. BrontoDB also adapts to changing data formats and queries and can optimize on the fly as the shape of your data and queries change – it never ‘blows up’ from a cost or latency perspective.
We believe that in an AI world, telemetry will be searched far more often, by both people and agents. So we made a deliberate design choice: Bronto parses, structures, and indexes data at ingest, paying that cost once per event instead of on every query. As search volume grows, that choice keeps queries fast and costs predictable.
The result is always fast AND efficient search for all your data, stored cost effectively, for as long as you want, with no manual configuration and all provided as a fully managed SaaS solution.
In contrast, many observability systems rely on users to know their data: defining parsers and mappings, and deciding what to index at ingestion – changing those choices later as data or query patterns evolve is costly and creates operational difficulties. ‘Indexless’ systems on the other hand rely on parallelising the scanning of data at search time – swapping a cost based on storage of indexes (paid once, continuously, whether or not you query) to a cost based query compute (paid per search, proportional to bytes scanned).
At Bronto:
We do not just offer indexing – we build several custom-built indexes automatically and store them efficiently
We do not just scan the data in parallel, but we reduce the data to scan using our indexes and apply custom parallel algorithms.
We adapt the format and index to each signal, and so search is fast on data you never previously anticipated querying and also on data that has been changed, e.g. by adding new keys
We store for 12 months with all data hot and indexed
Put another way – no schema to define, no index to configure, no cliff edge when handling an incident, i.e. when the available data falls outside what you optimized for or paid to retain.
What do you mean by Polymorphic Database?
‘Polymorphic’ stems from object-oriented programming. Polymorphism is the idea that a single interface can have many different implementations behind it: you call the same method on a shape object and the right code runs depending on whether it's a circle or a square. The caller doesn't need to know or care. One consistent surface, with many specialised internals.
BrontoDB applies that idea to storage. You send us logs, traces and metrics, query them all with the same SQL, and alert on them the same way. Behind that single interface, each signal is stored in a format built specifically for it — where each signal gets a representation tailored to its own shape.
The Architecture diagram below shows that unified Bronto system using the same ingestion and search layers with the different data types of logs, traces and metrics – each data frame gets an internal representation tailored to its intrinsic characteristics and on the historical access patterns of that data. As well as using the same SQL to query data, the reuse of the ingestion, alerting and search components provides economies of scale that we can pass on in our low per GB cost.
The polymorphic database removes the need to scatter observability data across different tools (providing a seamless UX across signals) or use a sub-optimal platform that was designed for one type of data.
The polymorphic database sits behind a rich fully public search API which also means that Bronto can make all your data available in every way now expected in an AI age, e.g. via the Bronto UI, API, MCP, Bronto Vibe, AI SRE, Agents etc. Data can also be enriched with additional context like patterns and anomalies for example, to make it inherently more useful for RCA and MTTR – AI SREs especially appreciate this additional context and data enrichment.
Why did you build your own Database (and not just use an existing one)?
As we said above, the Multidimensional Nature, Changing Environment, and Growing Volume in observability data pose significant challenges to databases. Existing storage technologies have been built around certain assumptions: that your data is structured or that it's not; that cardinality is low or that schemas don't change.
Real observability data breaks all of these assumptions: it is multidimensional and changes over time. Logs vary in structure, cardinality, repeatability and volume. Most data will evolve over time as new attributes and data streams are generated by evolving business needs or the different needs of your DevOps vs your Business Analytics teams. The introduction of new data means new searches that were not anticipated. The technologies that power the most popular observability stores provide great benefits under specific circumstances: think columnar for structured data, Bloom filters to skip blocks on full-text lookups, inverted indexes for sparse search etc, but they tend to use a single and/or static storage strategy and struggle to serve all or changing data shapes.
ClickHouse is a great example of this. ClickHouse is extremely fast when your data is well-modelled and your questions are known in advance. When the questions change, performance depends on design decisions that are costly to revisit, so it speeds up the questions you planned for, not the ones you didn't, which is a major issue for a general purpose observability platform. While ClickHouse also uses a familiar query language in SQL and in its open source form has zero licensing costs, the disadvantage is that it needs significant engineering investment to work for all logs, all the time, at scale, particularly as a lot of fixes seem to be for its Cloud only. For example, the open source version still has manual sharding and no compute separation – true serverless, autoscaling compute separation is a ClickHouse Cloud feature.
Another common approach is a dedicated datastore per signal — Prometheus for metrics, Elasticsearch for logs, Grafana Tempo for traces — based on the logic that a system optimised for one type of data gets slow and expensive when pushed to handle another. However, this makes correlating signals a headache: matching a metric spike against a burst of errors means jumping between UIs, query languages and mental models, usually while something is on fire. Imagine, the poor on-call engineer handling an incident at 2am who has to jump across tools, each with their own UI and maybe even a new query language and where the data they need may not have been indexed or may no longer be retained.
In contrast, we wanted control over our core DB technology to solve those challenges and not be restricted by the assumptions that some other storage technology had made, i.e. we wanted to take a polymorphic approach and provide a custom built store for observability data with always hot data, long-term retention and fast search at low cost – and that always has these characteristics, even as your data, queries and volumes change. We also wanted to provide users with one system for all their observability data, with a seamless UX across all signals - i.e. using the same SQL for queries across all their data and the ability to set alerts across all signals in a uniform manner.
So, we designed a purpose-built system that accommodates the challenges of observability data. This architecture adapts to your logs, so we do not force you to define schemas upfront or perform complex transformations before ingestion for logs. For traces, we use the same storage technology as logs and for metrics we have custom formats that allow us to handle high cardinality and store large volumes of point data very efficiently.
What does BrontoDB solve?
It is one platform and architecture for logs, traces and metrics to address the Multidimensional and Changing nature of observability data.
For traces and logs, we solve:
Fast Search
Custom automatic Indexing – all data is indexed
Bloom Filter, custom Summary Index and custom Partition Index
Applied automatically so users do not have to worry about managing indexes
Custom Columnar storage
Custom search algorithms adapted to analytics or event search
Parallel search that can scale massively using serverless if needed for large queries
All data is hot in our tiered storage
Custom store for pre-computed alerts and repeated queries, such as alerts or dashboards or common queries
Changing log formats by Adaptation
Structures Change – we adapt storage at ingestion, automatically adapt parser for types of log data
Adaptive Columnar formatting
Searches change – we adapt indexes, update pre-computed queries
Growing volume
Efficient custom columnar storage with high compression giving low-cost storage
Massively parallel search as data volumes grow
For metrics, we solve:
Fast Search
Purpose-built time-series structures to store metrics – these are selected based on OpenTelemetry’s point kind, cardinality, and volume
Columnar is the base format for real-time processing as it requires low effort and handles high-cardinality values well.
Partial aggregations are pre-computed and stored
Growing volume
Efficient custom columnar storage with high compression – low-cost storage
An offline compaction process runs periodically on the stored files to keep search fast as data accumulates.
Uses dedicated structures that have been designed to optimize matching and filtering at search time while reaching extreme compression factors.
Massively parallel search as data volumes grow
What do you mean by “fast search” at scale?
The multidimensional nature of observability data makes it hard to provide useful comparisons of search on different datastores, as there are many things which affect search such as types of log, shape of the data, types of search as well as the product configuration options and hardware used.
Publicly available reference numbers are also hard to come by at scale, with most published benchmarks operating at the GB to low-TB level. For context, independent tests on legacy solutions like CloudWatch Logs Insights report multi-second query times on datasets measured in millions of records or single-digit GBs, while Grafana publicly report Loki peak query throughput >1TB/s. In a published 212 GB benchmark, Quickwit measured Loki taking 9.3s for a full-text search and 90s for a full-dataset aggregation, versus 0.6s and 2.1s respectively for Quickwit. Quickwit separately demonstrates sub-second indexed search across 23 TB. Modern engines such as OpenObserve have published results with sub-second queries at ~2 TB on specific hardware (outperforming ClickHouse which had some ~1–2 second analytical queries) and they also report outperforming Elasticsearch in queries using their benchmarks.
The table below demonstrates how Bronto provides interactive search on real production workloads at a very different scale: 100–500+ TB, including 112 TB in under 10 seconds and 509 TB — more than half a petabyte — in 28 seconds. More specifically, this table shows a number of real user log searches run on Bronto over the past few weeks. It shows what you can expect as a Bronto end user in ‘the real world’. Note that every query returns quickly whether across hundreds of GB to TBs (milliseconds), from 10’s of TBs to over 100 TB (seconds) and even in the case of searching across ½ PB of data (less than 30s), showing the benefit of our indexes, which can skip up to 94% of data across all queries on a daily basis.
Stay tuned as we publish repeatable head-to-head benchmarks in future posts.
Data set size | Query type | Search duration (ms) |
630 GB | Columnar filter with group-by (pre-computed) | 117 |
467 GB | Filter on multiple columns | 266 |
1 TB | Filter on key=value, count of events | 133 |
36 TB | No filter, count of events by status (info / warning / error) | 1,459 |
11 TB | Full-text search with group-by | 3,623 |
112 TB | IP address full-text search with group-by IP address | 9,493 |
509 TB | IP address full-text search | 28,048 |
Bronto also achieves excellent compression of metrics, e.g. by how it handles repeated values and sequences of timestamps being the same across multiple time series. For example, we see certain high volume metrics in production being stored at roughly 0.3% of their original size, a compression factor of about 330x – 1 GB of data (more than 50 million points) fits in a 3 MB object.
What do you mean by “without compromises”?
Typically, observability teams have to choose between fast search or low cost, between having high-cardinality metrics or reducing costs, between cost and longer retention, between having indexes or rehydrating data. For many teams, this means they have to accept high costs or compromise on how much of their data they can analyse or how fast they can search it.
We built Bronto to provide fast search with low-cost storage of $0.10 per GB with 12 months hot data retention, regardless of the data being logs, traces or metrics.
As a result, Bronto:
Can save teams up to 90% of their observability spend
Provides teams with access to all their data for as long as they need it and it is always indexed for fast search speed – making it inherently more valuable for Agentic use cases and driving better outcomes
Reduces toil for users as indexing is done automatically as is log parsing
Provides a seamless unified UX for searching, alerting and analysing all your logs, traces and metrics in one place
BrontoDB Architectural Principles
Unified Architecture for Scalability
Storage uses common ingest and search
Monitors apply across logs, traces, metrics
Stateless Services to enable horizontal scalability
Decoupled Storage and Compute
Dedicated servers or serverless for search
Dedicated servers for alerts
Storage in File System or Object Store
Precompute as much as possible
Alerts, dashboards, repeated queries
API-first and RESTful APIs
Minimize user toil, e.g. automatic index creation, automatic log parsing
Same RBAC across services, including MCP server
Use of SQL as our Query Language across logs, traces, metrics
BrontoDB Architecture Layers
BrontoDB has 3 logical layers – Custom Columnar, Search, and Adaptation; which reflects how we break down the Multidimensional challenge of observability data. The 3 layers are shown in the following diagram and are explained in the following sections.
Custom Columnar storage layer
This layer provides custom columnar storage for each signal type (logs, traces, metrics) and solves known scale issues for each. As discussed, Logs have a huge variability in formats and access patterns, so Bronto tailors the data structure, automatically creates indexes and applies custom parsers to each case. Similar adaptive technology is used for Traces, leveraging the more predictable format (compared to logs) and the common access patterns. Metrics data is more predictable in shape and volume, so that is stored in dedicated data structures, with the format chosen automatically based on metric type, cardinality, and volume. The following table summarises how BrontoDB stores each signal type:
Source | Partition | Storage |
Logs | Logs stored in a timestamped set of files | Uses Bronto’s “adaptive columnar format” which uses a storage format based on whether log is structured (includes traces), semi-structured or unstructured
Distinguishes between frequent/infrequent keys and treats message body separately if log is not structured Automatically creates index files |
Traces | Traces stored in a timestamped set of files | Stored using same “adaptive columnar format” as logs |
Metrics | Metrics stored in a timestamped file | Stored initially as Columnar and converted to MultiPointColumnar |
BrontoDB’s log encoders automatically create a range of lightweight indexes that adapt to the log events ingested. Just as no single format fits all data, no single index does either. Bronto indexes are tailored to the log data and are built automatically at ingestion. BrontoDB uses these indexes to maximise the skip factor (the share of data that can be ignored while searching) on the widest possible set of queries, while being lightweight in terms of size and lookup speed.
Search Layer
BrontoDB uses different search techniques to ensure search is always fast, including the following:
Custom automatic Indexing – all data is indexed
Bloom filter, our custom Summary Index and custom Partition Index
Custom search algorithms adapted to the characteristics of search
Analytic searches need to consider all the matching data, but use the indexes to skip non-matching data and avoid a full scan of all the data
Event search needs to return matching events in time order
Custom store for pre-computed alerts and queries, such as alerts and dashboards
BrontoDB's serverless architecture and custom parallel algorithms scale out rapidly to massive compute, so every scenario gets a fast answer.
Complemented by a custom algorithm to grant serverless resources fairly
Our parallel search can use thousands of lambdas if needed for large searches, because some queries are simply unexpected (so cannot be pre-computed), complex and/or data-heavy meaning that even optimised storage may need significant compute resources to return timely results.
Adaptation Layer
This layer adapts how data is stored and indexed and handles changes to data formats and query patterns. BrontoDB implements three main layers of adaptability:
Parser adaptation: to enrich, standardize and identify values encoded in the data.
Layout adaptation: to partition and/or aggregate streams of data based on known access patterns, learned over time
Format adaptation: to serialize and index each data frame based on the data format
Parser adaptation
Bronto automatically parses logs to normalize and enrich the data. While the log message is not altered and is returned in its ingested form when searching, extra key-value pairs are extracted and indexed at ingestion to facilitate and speed up searches.
The most common parsers are built-in and applied automatically to well-known streams of data. For custom logs that follow no standard format, Bronto uses AI models to generate a parser, then validates its output before applying it to your logs.
Layout adaptation
Bronto observes search patterns for heavy or repeated queries. Repeated queries, such as from dashboards or scheduled jobs, get pre-computed and served in milliseconds, with no compute resource needed at search time.
Heavy custom queries get accelerated through partitioning. Bronto learns the most common filters and organizes the data accordingly. Partitioned objects carry data summaries and dedicated indexes, so queries are answered directly from summaries or skip data if there is no match.
Partitions and pre-computed queries are reevaluated periodically, so the layout keeps following your search patterns as they evolve, with no manual tuning required.
Format adaptation
Serializing and indexing incoming data happens at ingest time. Bronto supports a wide range of formats which can be grouped in three main categories:
Structured, repetitive logs and traces are stored in columnar format; the proven, most efficient choice for that shape of data.
Unstructured and semi-structured logs are parsed to extract meaningful key-value pairs. Frequent keys and rare or sparse keys are treated separately, avoiding the column explosion that affects other storage options. The message body is treated separately for unstructured logs.
Metrics are stored in purpose-built time-series structures, selected based on OpenTelemetry’s point kind, cardinality, and volume.
Columnar is the base format for real-time processing as it handles high-cardinality values well.
An offline compaction process runs periodically on the stored files to keep search fast as data accumulates.
Why BrontoDB reshapes Observability
Bronto was designed from the ground up to tackle the challenges of observability data:
One unified system. Logs, metrics and traces have genuinely different characteristics in shape and behaviour, but they describe the same system. BrontoDB's polymorphic engine is what makes that one store efficient, adapting to each signal instead of forcing them all into one format.
Consistent query performance. Fast searches regardless of the query or the volume involved. No cliff edge for users when a question falls outside what the system has been optimized for.
Automatic, lightweight and targeted indexing. Observability data arrives as high-volume, real-time streams that must be stored efficiently. Indexing data is about finding the sweet spot between ingestion costs and search speed and Bronto finds that sweet spot for you.
We provide three complementary indexes, chosen automatically per data frame, that between them skip most of your data on many queries — and answer some queries without reading any column data at all, by using pre-computed values.
Zero configuration. Send your data, Bronto handles the rest. No schemas to define, no index to configure and little operational effort required. The only configuration needed is on your agent – point it to Bronto and start querying.
High cardinality is handled. No more bills that punish you for cardinality. Bronto adapts to it with dedicated strategies rather than forcing you to change the data. The store should adapt to your data, not the other way around.
Pricing. Our unified architecture allows low cost, simple pricing across logs, traces, and metrics making it predictable for you – your bill scales (and does not explode!) with data volume.
Now, go and see how well Bronto works on your data, try it here or book a demo with our team!
Try Bronto free for 14 days
Centralize your agent and infrastructure telemetry in one platform with sub-second search and 12-month hot retention. No credit card required.